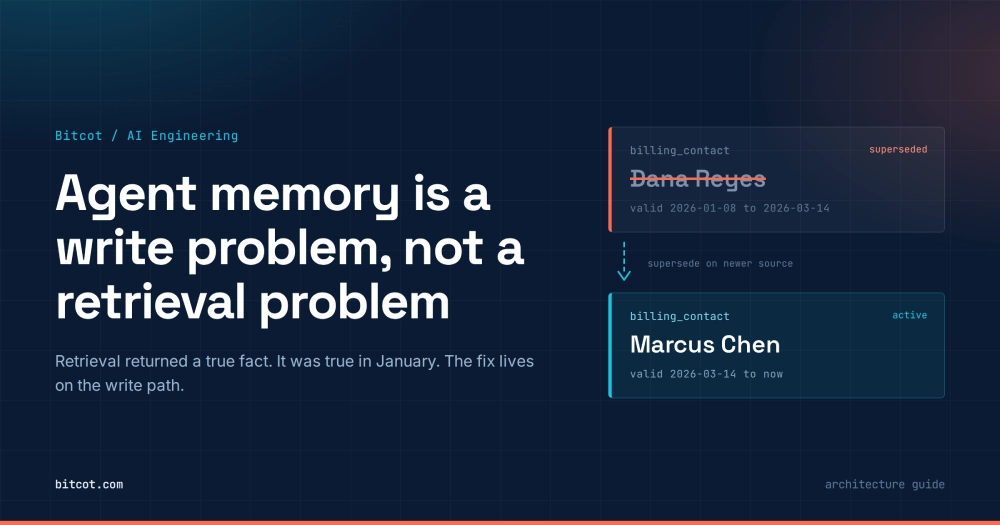
Follow one fact through an agent’s memory: how it gets written, why it quietly goes stale, what it takes to retire it, and the template that makes the whole thing repeatable from one client to the next.
Key Takeaways
- Most memory failures start on the write side. Retrieval usually works fine. The real problem is that corrections never become facts and outdated records are never retired.
- Supersession keeps answers current. Marking old records invalid with validity windows, instead of deleting them, stops stale facts from competing and still answers point-in-time questions.
- Tenant isolation belongs in the storage, not the query. Filters protect queries, but derived artifacts like summaries and caches can still leak data unless every one carries its tenant tag.
- A shared record schema makes memory repeatable. With one record contract and a per-client configuration file, the next deployment becomes configuration rather than a rebuild.
Introduction
Month four. Northwind Industrial runs its service contracts on a multi-tenant SaaS platform, and that platform ships an operations copilot. An account manager asks who the renewal for the Acme North account should go to. The copilot answers immediately: Dana Reyes, billing contact, and it helpfully includes her email address.
Dana left Acme in March. The account manager had said so, to this copilot, in a Tuesday conversation that went fine at the time. The correction is still sitting there, six turns into a transcript the system dutifully stored and never looked at again.
Retrieval did not fail. It ran, it scored, it returned the highest scoring record about billing contacts at Acme North, and that record was true. It was true in January.
The account, the vertical, and the names are a composite drawn from several engagements. The architecture, the failure modes, and the timelines are the real ones.
This is the shape of nearly every agent memory problem we get called into. The retrieval layer is competent. The write path never converted a correction into a fact, never retired the record that fact contradicted, and had no mechanism by which it could have. Teams then spend their engineering budget tuning rerankers, which is the one place where there was nothing wrong
The structural reason is worth naming. Retrieval augmented generation was designed for a corpus somebody else curated and froze, so the hard problems are chunking and ranking. Memory is a corpus the agent writes to, continuously, from noisy conversational input, where old records stop being true and nobody retires them. Same retrieval machinery, completely different failure surface.
What follows tracks a single claim, the billing contact for Acme North is Dana Reyes, from the turn that created it to the day the copilot finally answers correctly. Around that thread sits the architecture: the memory classes worth separating, the write pipeline that turns transcripts into retrievable facts, the read pipeline that decides what earns space in the prompt, and the configuration template that lets the same design ship to the next client in days rather than months. Implementation notes cover RAGFlow, which now has a native memory module, plus the equivalent stacks you would choose instead.
Four ways this breaks, and why none of them are bugs
Nothing in that opening scene was a defect. Every failure below is the structural consequence of a decision that looked entirely reasonable when it was made.
1. The agent retrieves what sounds similar, not what is true
The Tuesday turn contained a greeting, a scheduling aside, a complaint about a delayed shipment, and one sentence retiring Dana. Embedded whole, the vector represents the average of those things, and that average does not look much like a question about billing contacts. Raw turns embed badly because a turn is not a unit of meaning. Retrieval quality collapses well before the corpus gets large.
2. Nothing ever becomes false
The January record naming Dana was never marked wrong, because nothing in the system was capable of marking it wrong. Both the January statement and the March correction sit in the store, both embed near the query, and the reranker picks on semantic similarity, which cannot distinguish current from superseded. The agent answers with whichever scored higher. Without an explicit supersession mechanism, memory accuracy degrades monotonically as the store grows. Month one looks great. Month twelve is the problem.
3. Memory eats the context window
The team’s first fix was to raise top-k from 5 to 20, on the theory that the March turn would now make the cut. It did. The copilot saw both the March turn and the January record, and answered with January anyway, at roughly three times the prompt cost. Prompt size climbs, latency climbs, and answer quality often drops, because the model now has to find the relevant fact inside a wall of loosely related ones. Memory without a token budget is a cost line that grows with tenure.
4. Memory leaks across tenants
This one did not surface in month four. It surfaced during the rebuild, and it is covered in full further down, because it is the failure with actual legal weight. The short version: isolation was a metadata filter applied at query time, and a nightly job that summarized across tenants never went through the query path at all. Filters protect the query. They do not protect anything the system derived from more than one tenant’s data.
Three of the four happen on the write side, and the fourth happens outside the query path entirely. The leverage sits in what gets written, in what shape, and with what lifecycle. Design the write path first, and the retrieval work that follows is ordinary engineering.
Where should the Dana claim have lived?
Ask that question and the taxonomy answers itself. The claim is a stable attribute of an account, so it belongs in a semantic store where records are superseded rather than aged out. The Tuesday conversation that produced it is raw, kept for audit. The fact that a contact changed hands in March, and that the renewal slipped as a result, is episodic. The account manager’s standing instruction to always copy the regional lead on renewals is procedural.
None of those distinctions existed in the month four system. Everything went into one store, which is the root of most retrieval noise. Cognitive science offers a taxonomy that turns out to be operationally useful here, and it is the same split RAGFlow adopted in its memory module. We run five layers.
| Class | What it holds | Write trigger | Lifetime | Store |
|---|---|---|---|---|
| Working | The live turn window, scratchpad, tool results in flight | Every turn | Session | Runtime state, Redis |
| Raw | Verbatim transcript and tool call log | Every turn, append only | Retention policy | Postgres or object storage |
| Semantic | Stable facts, preferences, entity attributes | Post turn extraction | Until superseded | Vector plus relational |
| Episodic | Events with time and outcome, “what happened when” | End of task or session | Decays with age | Vector plus time index |
| Procedural | How this user or org wants things done, playbooks, corrections | On correction or success | Versioned, long lived | Vector plus version table |
The separation earns its keep in three places. Retrieval can query only the classes a given question needs, so “who is the billing contact” never competes against a year of episodic noise. Each class gets its own decay rule, so a slipped renewal from last March fades while a billing contact does not. And deletion becomes tractable, because a request to erase a person maps to a set of records rather than to “somewhere in the embeddings.”
Knowledge base RAG sits alongside these, not inside them. Product documentation, policies, and contracts are authored content with an owner and a review process. Keep that lane separate and retrieve from it in parallel. Mixing authored knowledge with agent-generated memory in one index makes provenance impossible to reason about, and provenance is what you need when a regulated client asks why the agent said what it said.
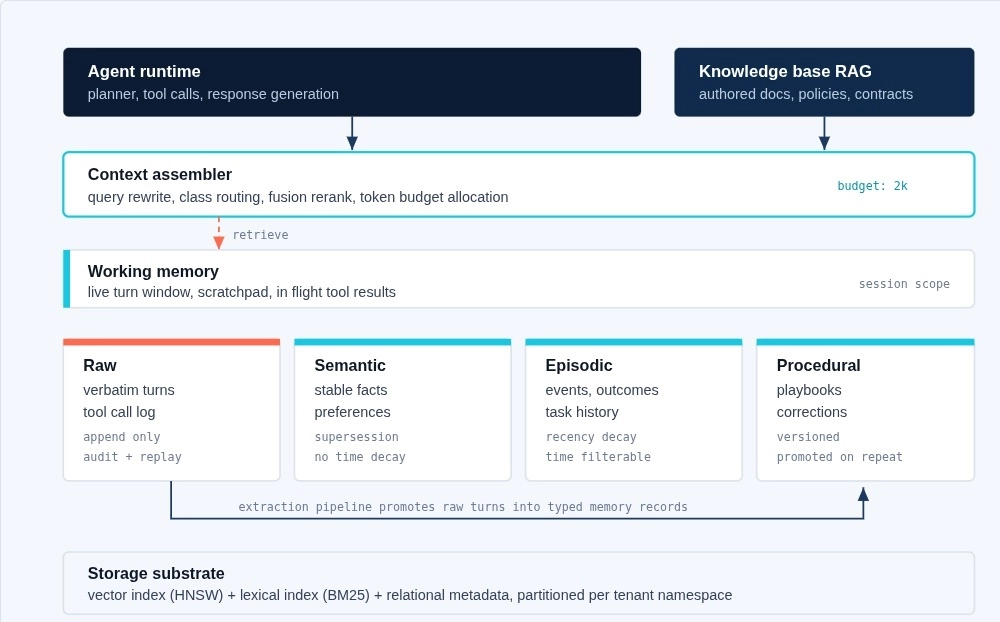
Figure 1. The memory stack. The Dana claim belongs in semantic, the Tuesday transcript in raw, the slipped renewal in episodic. Working memory lives in the runtime. Knowledge base RAG runs as a parallel lane so provenance stays clean.
The write path is the product
Here is the pipeline that should have run when that Tuesday turn completed, and did not. It is asynchronous, it is idempotent, and every stage is a place you can raise or lower quality deliberately. Stage 4 is the one that was missing.
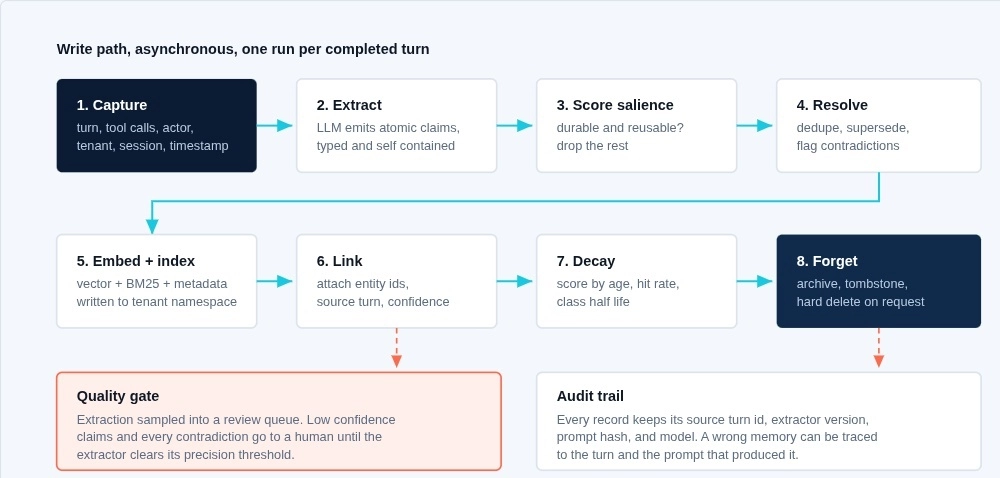
Figure 2. The write path. Stages 2 through 4 are where memory quality is won or lost, and stage 4 is the one the month four system did not have. Most teams skip straight from capture to embed, which is why their memory retrieves noise and never retires anything.
Extraction: atomic, self contained, typed
The extractor takes a turn and emits zero or more claims. Run the Tuesday turn through it and the sentence “Marcus Chen is taking over billing, Dana’s last day is Friday” should come out as two separate records, one naming the new contact and one dating the departure. Three rules make that reliable.
- Atomic. One claim per record. The Marcus sentence is two, because a query about who to invoice should not have to match against a sentence that is half about a departure date.
- Self contained. No pronouns, no “the same as before.” A claim that reads “he is taking over billing” is worthless at retrieval time, because the turn that named him is not in the prompt. The record has to say Marcus Chen, at Acme North, for billing.
- Typed at write. The extractor assigns the class, the subject entity, and a confidence. Classifying at read time means running an LLM call inside the latency budget of every request, which nobody does twice.
Salience scoring is the cheapest quality lever available. Ask the extractor a second question about each claim: will this still matter in thirty days, and would an agent need it to answer a future question. The Marcus claim passes both. The complaint about the delayed shipment passes neither, and writing it to the semantic store only means it competes for a top-k slot later. Most conversational content fails both tests. Writing only what passes typically shrinks the store by a large factor and improves retrieval precision at the same time, because precision is largely a function of how much irrelevant content is competing for those slots.
Conflict resolution and the memory lifecycle
This is stage 4, and it is where month four was decided. When a new claim arrives, compare it against the nearest existing records for the same subject and predicate. Four outcomes, and each needs an explicit rule.
| Outcome | Condition | Action |
|---|---|---|
| Duplicate | Same subject, same predicate, same value | Increment reinforcement count, update last seen, write nothing new |
| Refinement | Same subject and predicate, more specific value | Supersede the old record, link it as the predecessor |
| Supersession | Same subject and predicate, different value, newer source | Mark old record invalid from the new timestamp, keep it for audit |
| Contradiction | Different value, similar confidence, unclear ordering | Hold both, flag for review, exclude both from retrieval until resolved |
The Marcus claim lands squarely in row three. Same subject, same predicate, different value, newer source. The January record naming Dana gets a valid_to of March 14 and stops being retrievable as current, in the same transaction that writes the new one.
Notice that nothing is deleted. Records carry a validity window with a valid_from and an optional valid_to, which is what makes point in time questions answerable. “Who was the billing contact when we issued the February invoice” becomes a filtered retrieval rather than a guess, and in a dispute that distinction is the whole ballgame. This bi-temporal pattern (transaction time plus validity time) is the single most valuable structural addition to a memory store, and it is the core of what temporal knowledge graph products like Graphiti provide.
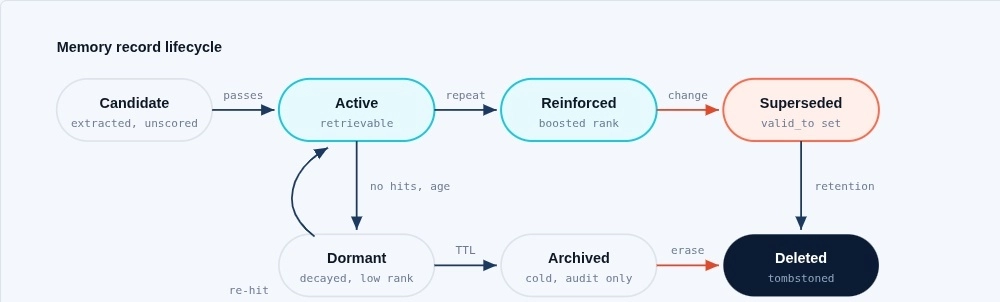
Figure 3. Records move through states rather than being created and forgotten. The Dana record moves to superseded, not deleted, which is why February invoice questions still answer correctly. Dormant records can be revived by a hit, and deletion leaves a tombstone so downstream caches can be invalidated.
The read path: retrieval is a budgeting problem
With supersession in place, the January record is excluded in the semantic lane before anything is scored, so it never competes for a slot and no amount of similarity can resurrect it. That is the whole fix for month four, and it happened on the write side. What is left is routine engineering, plus the part teams underinvest in: deciding what actually earns a place in the prompt.
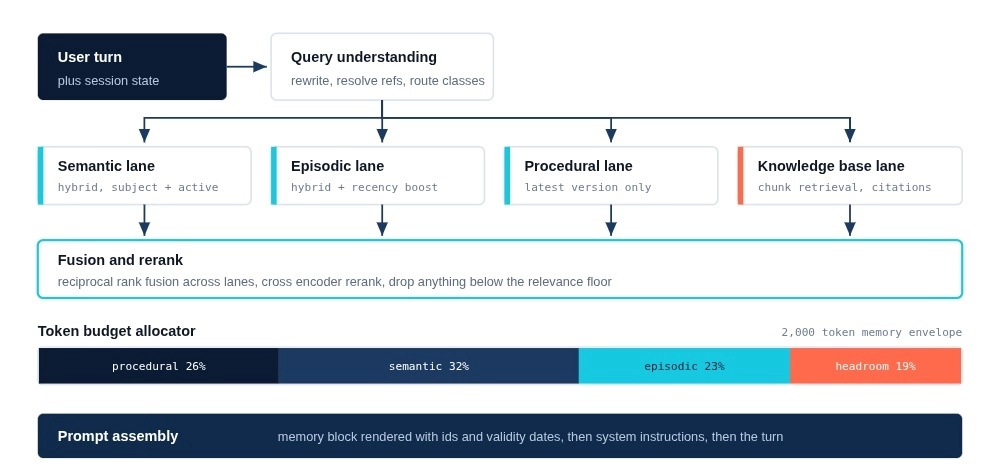
Figure 4. The read path. The superseded Dana record is filtered out in the semantic lane before scoring, not after. Class routing runs lanes in parallel, fusion reranking merges them, and a fixed token envelope keeps memory cost flat as the store grows.
Four rules that make retrieval hold up
- Hybrid, always. Dense vectors miss exact tokens (order numbers, SKUs, error codes) and lexical search misses paraphrase. Run both and fuse. Reciprocal rank fusion is a reasonable default and needs no score calibration.
- Filter before you search, not after. Tenant, subject, class, and validity should be predicates pushed into the index, not a post-filter over top-k. Post-filtering silently degrades recall, because the filtered-out results already consumed the slots.
- Fix the envelope, vary the contents. Give memory a fixed token budget per turn, split across classes. When the store grows, the competition inside the envelope gets tougher, and cost stays flat. This is the difference between a system that stays economical at year three and one that does not.
- Render provenance into the prompt. Each memory line carries a record id, a validity date, and a confidence. It costs a handful of tokens and it lets the model say “as of March” instead of asserting stale facts as current, and lets you trace any output back to a record.
The memory record: one contract, every deployment
Here is the record the March turn should have produced. Note supersedes: it points at the Dana record, which is still in the store, still carries its own validity window, and still answers February questions correctly.
Templatization starts here. If the shape of a memory is identical across clients, every downstream component (extractor, resolver, retriever, evaluator, admin console) is reusable, and a new engagement becomes configuration rather than construction.
{
  "record_id": "mem_01J8X4K2P",
  "tenant_id": "northwind",
  "subject_id": "acct_4412",
  "class": "semantic",
  "predicate": "billing_contact",
  "claim": "Billing contact for Acme North is Marcus Chen, [email protected].",
  "structured": { "name": "Marcus Chen", "email": "[email protected]" },
  "confidence": 0.91,
  "salience": 0.82,
  "valid_from": "2026-03-14T16:41:00Z",
  "valid_to": null,
  "supersedes": "mem_01J2Q9F7B",
  "source": {
    "turn_id": "turn_88213",
    "session_id": "sess_5521",
    "channel": "ops_copilot"
  },
  "provenance": {
    "extractor_version": "v4",
    "prompt_hash": "9c1f0a",
    "model": "claude-sonnet-4-6"
  },
  "sensitivity": "pii",
  "reinforcement_count": 3,
  "last_retrieved_at": "2026-09-09T14:03:00Z",
  "state": "active"
}
On Postgres with pgvector this maps to a single table plus indexes, which is where we start most engagements because the operational burden is close to zero and it can carry a surprising amount of load.
CREATE TABLE memory_record (
  record_id           text PRIMARY KEY,
  tenant_id           text NOT NULL,
  subject_id          text NOT NULL,
  class               text NOT NULL,
  predicate           text,
  claim               text NOT NULL,
  structured          jsonb,
  embedding           vector(1024),
  claim_tsv           tsvector GENERATED ALWAYS AS (to_tsvector('english', claim)) STORED,
  confidence          real NOT NULL DEFAULT 0.5,
  salience            real NOT NULL DEFAULT 0.5,
  valid_from          timestamptz NOT NULL,
  valid_to            timestamptz,
  supersedes          text REFERENCES memory_record(record_id),
  source              jsonb NOT NULL,
  provenance          jsonb NOT NULL,
  sensitivity         text NOT NULL DEFAULT 'none',
  reinforcement_count int NOT NULL DEFAULT 1,
  last_retrieved_at   timestamptz,
  state               text NOT NULL DEFAULT 'active'
) PARTITION BY LIST (tenant_id);

CREATE INDEX ON memory_record USING hnsw (embedding vector_cosine_ops)
  WITH (m = 16, ef_construction = 64);
CREATE INDEX ON memory_record USING gin (claim_tsv);
CREATE INDEX ON memory_record (tenant_id, subject_id, class, state);
CREATE INDEX ON memory_record (tenant_id, predicate, valid_from DESC);
Partitioning by tenant is deliberate, and it is the first half of the answer to the leak described further down. It turns isolation into a physical property of the storage rather than a predicate someone has to remember to write, and it makes tenant offboarding a partition drop instead of a long running delete that leaves index debris behind.
The memory pack: what makes this templatized
Northwind is one tenant on one platform. The next engagement is a different vertical with different decay rates and a different definition of sensitive. The architecture above does not change. A configuration file does. We call it a memory pack, and it is the deliverable that turns a bespoke build into a repeatable one.
# memory-pack.yaml
pack: support-agent-memory
version: 2.3
tenant_strategy: namespace_per_tenant   # namespace | database | cluster

classes:
  semantic:
    enabled: true
    half_life_days: null          # stable facts do not decay
    retrieval_budget_pct: 32
    extraction_confidence_floor: 0.7
  episodic:
    enabled: true
    half_life_days: 45
    retrieval_budget_pct: 23
    extraction_confidence_floor: 0.6
  procedural:
    enabled: true
    versioned: true
    retrieval_budget_pct: 26
    promote_after_repeats: 2
  raw:
    enabled: true
    retention_days: 400
    retrievable: false            # audit only, never retrieved

retrieval:
  token_envelope: 2000
  headroom_pct: 19
  mode: hybrid                    # dense + bm25, reciprocal rank fusion
  rerank: cross_encoder
  relevance_floor: 0.34
  filters_pushed_down: [tenant_id, subject_id, class, state, valid_window]

write_policy:
  salience_gate: true
  conflict: supersede_on_newer_source
  contradiction_action: hold_and_flag
  review_sample_rate: 0.05

governance:
  sensitivity_classes: [none, pii, phi, financial]
  redact_before_embedding: [phi]
  erasure: cascade_to_derived
  audit_retention_days: 2555

models:
  embedding: text-embedding-3-large
  extractor: claude-sonnet-4-6
  reranker: bge-reranker-v2-m3
Everything a client engagement actually varies (which classes matter, how fast things go stale, what counts as sensitive, how much context the budget allows) lives in this file. The pipeline code does not change. Neither does the evaluation harness, the admin console, or the deletion flow. That is what makes the second deployment cost a fraction of the first, and it is the difference between selling an AI project and having a practice.
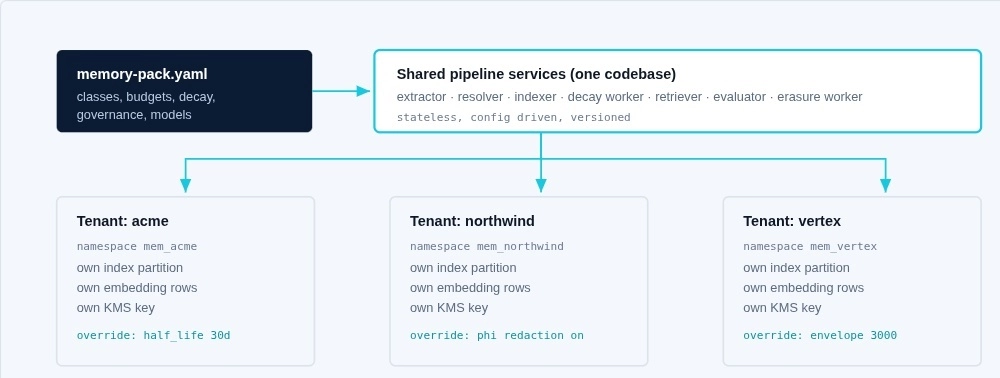
Figure 5. One pack definition, one set of stateless services, N isolated tenant namespaces. Per tenant overrides sit in the same schema, so a client-specific requirement never forks the codebase.
Implementing on RAGFlow
So where does this get built. RAGFlow added a native Memory module in version 0.23.0, and it maps closely onto the model above, which makes it a fast way to stand up the agent-facing layer without writing a pipeline from scratch.
What RAGFlow gives you
- Typed memory out of the box. Four types:
raw(required, the verbatim conversation),semantic(stable facts, preferences, attributes),episodic(time and event bound records), andprocedural(processes, habits, handling rules). Raw is the substrate the others are extracted from. - Two models per memory. An embedding model for retrieval and a large language model for extraction, configured on the memory itself. Changing them after messages exist is not recommended, which matters for planning: pin your embedding model before you load production data, or budget for a reindex.
- Extraction prompts you control. The system prompt defines the extraction role, output format, and structural constraints, and temperature (0 to 1) controls how stable the extraction is. Low temperature is the right default: you want the same claim phrased the same way every time so dedupe works.
- Agent wiring through components. The Message component writes to a memory via its save setting, and a Retrieval component reads from it. Both directions need to be configured explicitly; a memory that is written but not wired to a Retrieval component is never recalled.
- Visibility scope. Memories are scoped to “only me” or to the team, which is a useful coarse boundary for internal agents.
- Message-level control. Individual messages can be excluded from retrieval, and entries that have been actively forgotten stop appearing in agent calls and are prioritized for removal when the forgetting policy fires.
Where you will need to build around it
Capacity. Memory size is capped, with a maximum in the low single digit megabytes per memory, and the forgetting policy on offer is first in first out. FIFO is time ordering, not value ordering. On a busy tenant, a billing contact learned in week one is evicted before a throwaway shipping complaint from yesterday, which is the same class of failure as month four arriving from the opposite direction. For an assistant that accumulates knowledge over years, it is the wrong curve.
Storage type. The current storage option is table oriented, which suits general messages and field queries. Graph-shaped memory, where the value is in traversing relationships between entities, is not what this module is for.
Validity windows. There is no bi-temporal validity model, so point in time questions and clean supersession need to be modeled in your own layer.
The pattern we use is a split. RAGFlow Memory serves as the hot, agent-facing working and session layer, where its size cap is a feature rather than a limitation because it enforces a bounded context. The durable, tenant-scale semantic and procedural store lives outside it in Postgres with pgvector, or in the vector database the client already runs, and is exposed to the RAGFlow agent as a retrieval tool. Consolidation runs on a schedule: promote what proved durable in RAGFlow Memory into the external store before FIFO gets to it, and pull the top ranked external records back in at session start.
Two more RAGFlow features are worth designing around. The Agent API returns execution trace logs, which is what you want feeding your evaluation harness rather than reconstructing agent behavior from application logs. And on the knowledge base lane, parent-child chunking plus table of contents extraction address the recall-versus-completeness tension directly: retrieve on the small child chunk, hand the model the parent. Use both on document-heavy deployments.
Equivalent stacks and when to pick them
RAGFlow is one option. The memory layer market has consolidated into a few architectural bets, and the right choice follows from which problem dominates your deployment.
| Stack | Architectural bet | Pick it when | Main tradeoff |
|---|---|---|---|
| Postgres + pgvector | You own the schema, the lifecycle, and the indexes | Regulated data, existing Postgres operations, custom conflict rules, full portability | You build extraction, decay, and consolidation yourself |
| RAGFlow | Converged RAG and agent platform with memory as a module | Document-heavy agents where knowledge base RAG is the dominant workload and memory is secondary | Capacity cap and FIFO forgetting; no validity windows |
| Mem0 | Extract and retrieve as a drop-in API across frameworks | Fast path to per-user personalization; framework-agnostic; small context footprint | Timestamps without true point in time reconstruction; graph features tiered |
| Zep / Graphiti | Temporal knowledge graph with fact validity windows | Entity relationships that change over time, contradiction resolution, auditability | Heavier context footprint and graph infrastructure; hosted-first |
| Letta | Agent-managed memory, main context as RAM and archival as disk | Long-horizon autonomous agents that should curate their own memory | Adopting a full agent runtime, plus tool-call overhead per session |
| LangGraph + LangMem | Memory primitives native to an existing orchestration graph | You are already on LangGraph and want the least integration friction | Couples memory to the framework; backend performance is your problem |
Every vendor in this space publishes memory benchmark scores, commonly on LongMemEval. Those numbers move substantially when reproduced under independent harnesses, and the independent harnesses are frequently run by competing vendors. Treat published scores as directional evidence about architecture, not as a procurement input. Build a golden set from your own traffic and measure on that. It takes about a day and it is the only number that predicts your outcome.
Multi-tenant isolation, done properly
The near miss on this engagement had nothing to do with Dana going stale. A nightly job summarized recent account contact changes across the whole corpus to warm a cache, keyed on the text of the query rather than on the tenant. Marcus Chen’s email address was one cache hit away from appearing inside a different distributor’s answer. No retrieval filter was violated, because the leak path was never a retrieval.
This is where memory systems create real liability, and where retrieval-time filtering quietly fails. Four requirements.
Isolate at the index, not the query
Namespace per tenant, partition per tenant, or database per tenant depending on how many tenants and how strict the requirement. Credentials scope to the namespace. A query that forgets its tenant predicate should return an authorization error, not another tenant’s data.
Tag derived artifacts at creation
The leak path that filters do not cover is derivation, which is exactly what the nightly job was. A summarization job that reads across tenants to warm a cache, an evaluation set assembled from mixed traffic, a fine-tuning corpus, an embedding cached against text alone: all of these can carry tenant A content into a tenant B response without any query ever violating a filter. Every derived artifact inherits the tenant tag of every input, and an artifact carrying two tenant tags is a bug that should fail the build.
Make erasure cascade
A deletion request has to reach the record, its embedding, its supersession chain, every summary that consumed it, and every cache entry keyed on it. Model this before you launch, not after the first request arrives. The cascade is much easier to implement when every record carries its source ids from day one, which is the other reason the provenance block in the record schema is not optional.
Probe for leaks in CI
Plant a canary fact in tenant B, something shaped like a contact record so it exercises the same paths Marcus does. In CI, query with tenant A credentials for that fact, across every retrieval path and every derived artifact including the summarization and evaluation jobs. Fail the build on any hit. This is a half day of work and it is the only isolation control that keeps working as the codebase changes.
Measuring whether it works
Contradiction rate is the metric that would have surfaced month four in week two, for the cost of an afternoon. Four metrics on a frozen golden set built from real traffic, tracked per release.
| Metric | Definition | Why it matters |
|---|---|---|
| Recall at k | Share of queries where the required fact appears in the retrieved set | The ceiling on answer quality. If it is not retrieved, no prompt fixes it. |
| Contradiction rate | Share of responses asserting something the store disproves | Directly measures whether supersession is working |
| Staleness rate | Share of served records with a valid_to in the past |
Catches decay and forgetting failures before users do |
| Context cost | Median memory tokens per turn | Tells you whether the envelope is holding as the store grows |
Add one qualitative check that catches things metrics miss: sample twenty memory records a week and ask whether a human reading them cold would agree they are true, atomic, and worth keeping. Extraction quality drifts when models or prompts change, and it drifts silently.
Anti-patterns we see repeatedly
A realistic rollout
Six weeks is the honest timeline for a multi-tenant memory layer with write actions and an evaluation harness. Here is how that splits.
| Phase | Scope | Exit criteria |
|---|---|---|
| Weeks 1 to 2 | Record schema, raw capture, extraction v1, hybrid retrieval, single tenant, read only recall | Golden set built, recall at k measured, extraction precision reviewed by hand |
| Weeks 3 to 4 | Conflict resolution, validity windows, decay and forgetting, token envelope, admin view of records | Contradiction and staleness rates under target, context cost flat under load |
| Weeks 5 to 6 | Tenant namespacing, erasure cascade, CI leak probes, memory pack config, one guided write action behind approval | Leak probe green, erasure verified end to end, second tenant deployed from config alone |
The sequencing matters. Teams that start with multi-tenancy and write actions spend weeks on infrastructure before they learn whether their extraction is any good, and extraction quality is the thing that decides whether the project succeeds. If the extractor cannot reliably turn the Tuesday turn into two clean claims, nothing downstream saves it.
Month twelve
Same account, same question, rebuilt system. An account manager asks who the Acme North renewal should go to, and the copilot answers:
Billing contact for Acme North is Marcus Chen, [email protected], current as of March 14. Before that it was Dana Reyes. Standing instruction on this account is to copy the regional lead on renewals.
That is three sentences and it is the entire architecture reporting for duty. The contact came from the semantic store, current because supersession retired its predecessor rather than leaving both to compete. The March date came from a validity window, which is also why the February invoice question still resolves to Dana. The standing instruction came from the procedural layer, promoted after the account manager said it twice. Nothing else from twelve months of conversation made it into the prompt, because it did not clear the salience gate or did not win a slot inside the envelope. Marcus stayed inside the Northwind namespace throughout, including in the nightly summarizer, because the leak probe in CI would have failed the build otherwise.
None of that is a retrieval achievement. Every one of those properties was decided on the write side, weeks before the question was asked.
Frequently Asked Questions
What is the difference between RAG and agent memory?
RAG retrieves from a corpus someone else authored, such as policy documents or product manuals. Agent memory retrieves from a corpus the agent itself wrote during past interactions. RAG is read-only against curated content, so the hard problems are chunking and ranking. Memory is read-write against generated content, so the hard problems are extraction quality, contradiction handling, and forgetting. They share a retrieval layer but need different write paths and different governance.
Can I just store every conversation in a vector database and call it memory?
No. Raw transcripts embed poorly because a single turn mixes pleasantries, corrections, and facts into one vector. Retrieval returns turns that sound similar rather than facts that are true, and stale statements are never retired. Extract atomic, self-contained claims from transcripts, type them, resolve contradictions against existing records, and apply a decay policy. Keep the raw transcript for audit, but retrieve against the extracted records.
Does RAGFlow support agent memory natively?
Yes. RAGFlow added a Memory module in version 0.23.0. It supports four memory types, with raw required and semantic, episodic, and procedural available as extracted layers. Each memory has an embedding model for retrieval, a large language model for extraction, a configurable size cap, and a first in first out forgetting policy. Agents write through the Message component and read through the Retrieval component. The built-in memory is capped per memory, so tenant-scale durable stores usually sit outside it.
How do you keep memory isolated between tenants?
Isolate at the index or collection level, not at query time with a metadata filter. A filter is one forgotten predicate away from a cross-tenant leak, and it does not protect derived artifacts such as summaries, embedding caches, or evaluation sets that mixed tenant content during generation. Give every tenant its own namespace, scope credentials to it, tag every derived artifact with the tenant identifier at creation, and run an automated leak probe in CI.
How do you measure whether agent memory is working?
Measure four things on a frozen golden set: recall at k, contradiction rate, staleness rate, and context cost in tokens per turn. Track them per release. Public benchmarks such as LongMemEval are useful for calibrating an approach, but vendor published scores frequently fail to reproduce under independent harnesses, so build your own golden set from real traffic.
How long does it take to build a production agent memory layer?
For a single tenant with read-only recall, two to three weeks is realistic. For a multi-tenant deployment with write actions, extraction quality gates, contradiction handling, deletion and revocation flows, and an evaluation harness, six weeks is the honest number. The retrieval layer is rarely the bottleneck. Extraction prompts, conflict rules, and the isolation and deletion work consume most of the schedule.