- CNCF’s 2025 survey ranks team culture as the top adoption challenge.
- Measure progress with DORA’s five metrics, one value stream at a time.
- Give every roadmap phase an exit criterion before starting it.
- San Diego and Los Angeles teams stall most when tools precede baselines.
- Scale transformation only after the pilot value stream measurably improves.
A San Diego SaaS team can have every DevOps box ticked: pipelines run, builds pass, and dashboards are green. Yet enterprise DevOps transformation has not happened if releases still break billing, a third of each sprint goes to unplanned fixes, and nobody can say whether last quarter was better than the one before. The tools arrived, but the evidence never did.
The obstacle is rarely the technology. In the CNCF’s 2025 Annual Cloud Native Survey, cultural change within development teams became the top challenge for the first time, cited by 47% of respondents, ahead of training, security, and complexity.
This guide is written for the leaders who fund and govern the change. It lays out a seven-phase roadmap where every phase has an exit criterion, shows how to prove progress with DORA’s five delivery metrics, and explains why a transformation should scale only after one value stream has measurably improved.
What Is Enterprise DevOps Transformation?
Enterprise DevOps transformation is the organization-wide shift from handing work between separate development, operations, and security groups to a delivery system where teams own their services end to end, infrastructure is defined as code, and improvement is measured continuously. Adoption means installing DevOps tools; transformation means changing how decisions, ownership, and accountability flow.
The difference shows up in outcomes, not tooling. A team that adopted DevOps can deploy often; a transformed organization deploys often, recovers quickly, and can prove both with data. If you need the hands-on implementation checklist for pipelines and tooling, our guide to enterprise DevOps covers that ground; this article focuses on sequencing, governance, and measurement.
Why Do Enterprise DevOps Transformations Stall?
Enterprise DevOps transformations stall when leadership funds tools before defining what success looks like, so there is no baseline to improve against and no signal for when to change course. Four failure patterns show up again and again, and each one reinforces the others.
Goals Without Measures
Initiatives get approved with goals such as “ship faster” but no agreed metric or starting value. Teams then optimize whatever is easiest to count, usually deployment frequency, while change failures and rework climb unnoticed.
Architecture That Resists Automation
Tightly coupled services mean one bad deployment can ripple across the platform, so every release needs coordination and every pipeline needs manual gates. Automation layered on top of that coupling speeds up the failures rather than removing them, which is why many programs eventually need a planned microservices migration for their most change-heavy components.
Handoffs That Survive the Reorg
Security reviews still happen at the end, infrastructure still arrives through tickets, and operations still learns about changes after they ship. The org chart changed, but the queues between groups did not.
Incentives That Reward Speed Over Stability
Engineering leaders carry personal accountability for uptime and delivery dates, so pressure to show quick wins pushes teams toward shortcuts. Those shortcuts add technical debt that the next phase of the program then has to pay down.
How Should You Measure an Enterprise DevOps Transformation?
Measure an enterprise DevOps transformation with DORA’s five software delivery metrics, tracked for one application or service at a time and compared against that service’s own baseline. Organization-wide averages hide the teams that are improving and the ones that are sliding backward.
The metric set itself has changed recently. According to DORA’s own metrics guide, software delivery performance is now measured with five metrics split into throughput and instability, and its research shows speed and stability are not tradeoffs: top performers do well on all five, while low performers struggle on all five.
| Metric | Factor | What it tells leadership |
|---|---|---|
| Change lead time | Throughput | How long an approved change waits before users get it |
| Deployment frequency | Throughput | Whether releases are small and routine or large and risky |
| Failed deployment recovery time | Throughput | How quickly the team restores service after a bad release |
| Change fail rate | Instability | How often a release needs a rollback or hotfix |
| Deployment rework rate | Instability | How much delivery capacity goes to unplanned fixes |
Rework rate deserves the closest attention from executives, because it converts directly into lost roadmap capacity. A team whose deployment frequency doubles while rework rate also climbs has not improved; it has simply become faster at shipping problems.
The Seven-Phase Enterprise DevOps Transformation Roadmap, Gated by Evidence
An enterprise DevOps transformation roadmap works best as seven phases, each with an exit criterion that must be met before the next phase gets funding. The gates keep the program honest: when a phase does not move its metric, the team learns why before spending more.
| Phase | Exit criterion | Metric to watch |
|---|---|---|
| 1. Baseline one value stream | Five DORA metrics recorded for the pilot service | All five, as a starting point |
| 2. Platform engineering and IaC | New environments provisioned from code, without tickets | Change lead time |
| 3. DevOps Centre of Excellence | Shared standards adopted by the pilot team | Consistency across teams |
| 4. CI/CD and progressive delivery | Every release is small, gated, and reversible | Change fail rate |
| 5. DevSecOps | Security checks run in the pipeline, not at the end | Lead time held steady as checks increase |
| 6. Observability | Any failed release traced to its cause within one working session | Failed deployment recovery time |
| 7. Governance and FinOps | Metrics and cloud cost reviewed on a fixed cadence | Deployment rework rate |
Phase 1: Baseline One Value Stream
Pick one revenue-relevant service and measure it in production before changing anything. Map its pipeline, its manual steps, its dependencies, and its recent incidents, then record all five DORA metrics as the starting point.
Choosing a single value stream keeps the baseline honest and the scope small. For services still running on aging platforms, this is also where the team decides whether the pilot needs legacy application modernization work before automation can help.
Phase 2: Platform Engineering and Infrastructure as Code
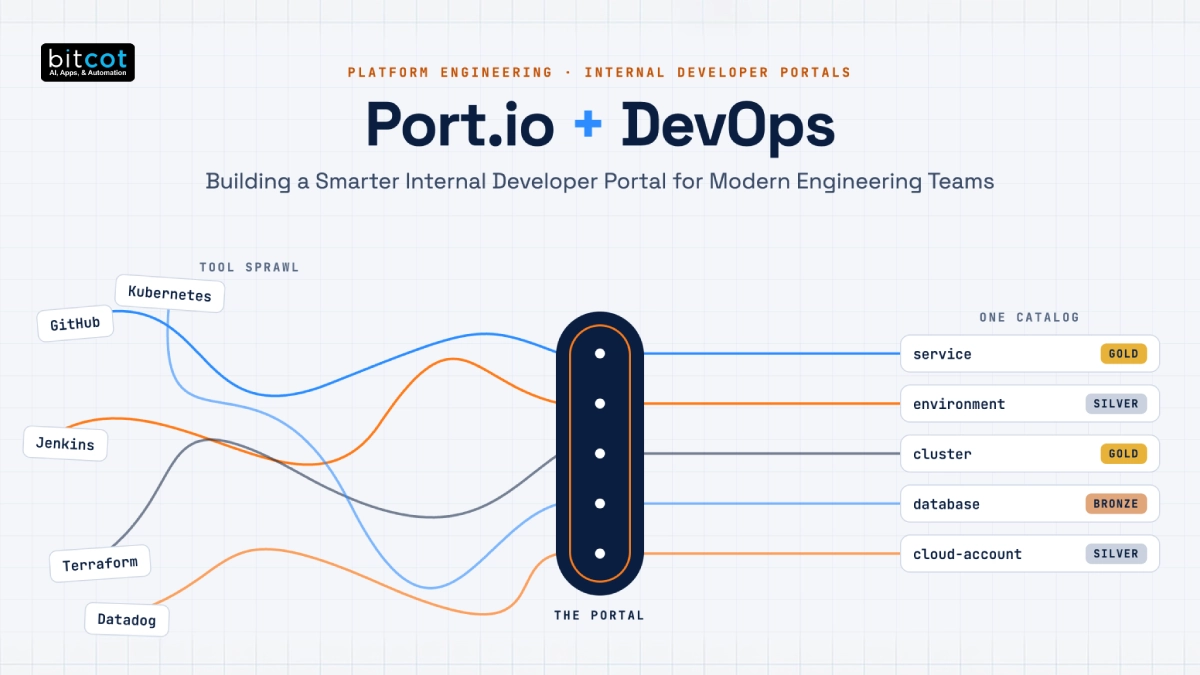
Platform engineering gives product teams a self-service internal developer platform with standard pipelines, environments, and guardrails, so each team stops rebuilding its own toolchain. Infrastructure as code with tools such as Terraform, and orchestration with Kubernetes, remove configuration drift and make environments reproducible.
The approach is becoming the default operating model for large organizations. Gartner expects 80% of large organizations to adopt platform engineering to scale DevOps in hybrid cloud environments by 2027, up from less than 30% in 2023.
Platforms work best when the services running on them were designed for the cloud. Teams building new services should follow cloud-native application development patterns such as stateless compute and managed services, so the platform can scale them without special handling.
Phase 3: Establish a DevOps Centre of Excellence
A DevOps Centre of Excellence (DCoE) is a small cross-functional group from development, operations, security, and QA that sets shared standards, curates the approved toolchain, and coaches product teams. Without it, every team invents its own pipeline and quality gates, recreating the fragmentation DevOps was meant to remove.
The DCoE should enable rather than approve. Its success is measured by how many teams adopt the paved path voluntarily, not by how many exceptions it rejects.
Phase 4: CI/CD Maturity and Progressive Delivery
A mature pipeline enforces quality gates, runs automated tests at unit, integration, and end-to-end levels, validates policy as code, and can roll a release back before customers notice. The goal of this phase is to make every release small, observable, and reversible.
Feature flags and canary releases do most of that work. New code merges into production behind a flag, then opens to 5% of users, then 25%, then everyone, with monitoring at each step; if error rates rise, the flag turns off without a redeploy. This is how teams raise deployment frequency while change fail rate falls.
Phase 5: DevSecOps and Pipeline Security
DevSecOps moves security checks into every stage of delivery: dependency scanning at build, secret detection in repositories, container image scanning before deployment, and runtime protection in production. Security becomes a property of the pipeline rather than a meeting at the end of the release cycle.
A shared vocabulary helps security and engineering agree on scope. The NIST Secure Software Development Framework describes a set of outcome-based secure development practices, drawn from sources such as OWASP, BSA, and SAFECode, that organizations can fit to their own business requirements and risk tolerance.
The exit criterion for this phase is that lead time holds steady as checks are added. If every new scan adds hours of waiting, the checks are running in the wrong place or blocking on the wrong severity.
Phase 6: Observability and Incident Response
Observability means the team can answer “what changed?” and “what broke?” quickly, without relying on the one engineer who remembers how the system works. That requires metrics, logs, and distributed traces tagged with release version and configuration, collected in tools such as Grafana, Prometheus, Datadog, or AWS CloudWatch.
Once that telemetry is clean and consistent, anomaly detection and automated remediation become realistic next steps, often built with AI/ML development on top of the incident history. Applied to noisy or incomplete data, the same models create false alarms and erode the team’s trust in alerts.
Phase 7: Governance, FinOps, and Continuous Improvement
Governance turns the gains into habits: the five metrics are reviewed on a fixed cadence, incidents get blameless reviews, and each review ends with one change to the system rather than a reminder to be careful. FinOps practices add cost visibility to the same reviews, so infrastructure growth stays tied to business value.
Cost governance often exposes workloads that were moved to the cloud but never adapted for it. Those are candidates for cloud modernization, where rearchitecting or right-sizing reduces both spend and operational load.
How Does Patchwork DevOps Compare to an Architected Transformation?
Patchwork DevOps adds tools to an unchanged delivery system, while an architected transformation changes ownership, structure, and measurement alongside the tools. The difference shows up across every dimension leadership cares about.
| Dimension | Patchwork DevOps | Architected transformation |
|---|---|---|
| Release pattern | Large, scheduled, coordinated releases | Small, routine, independently deployable changes |
| Failure handling | Manual rollback and war rooms | Feature flags, canaries, and automated rollback |
| Security | Manual review at the end | Automated checks at every pipeline stage |
| Infrastructure | Ticket-driven provisioning | Self-service platform defined as code |
| Measurement | Activity counts such as builds and tickets | Five DORA metrics per service, against a baseline |
| Cost control | Monthly bill surprises | Tagged resources reviewed alongside delivery metrics |
Should You Build DevOps Capability In-House or Work With a Partner?
Most enterprises get the best results from a hybrid model: an internal platform team that owns the long-term system, supported by an experienced partner that brings proven playbooks and helps the first value streams move faster. Fully outsourced programs tend to leave little capability behind, while fully in-house programs often stall on the learning curve.
| Factor | In-house only | Hybrid with a partner |
|---|---|---|
| Ramp-up | Paced by hiring and onboarding | Starts with engineers who have run the phases before |
| Breadth | Limited to current team skills | Architecture, cloud, security, and observability together |
| Governance | Built from scratch | Existing frameworks adapted to your context |
| Knowledge risk | Concentrated in a few people | Documentation-first with planned handoff |
The test of a good partner is what stays behind when the engagement ends. Effective DevOps consulting pairs partner engineers with internal owners on every phase, so the platform, the runbooks, and the metric reviews belong to your team.
Legacy estates add one more consideration. When core systems still run on premises, the roadmap should include a staged legacy application migration to cloud plan with parallel running, so no single cutover puts the business at risk.
Why Stalled Transformations Usually Skipped the Baseline
Across DevOps engagements for teams in San Diego, Los Angeles, and New York, the stalled programs we are asked to rescue share one trait: they bought a CI/CD platform before measuring anything. Months later, the pipeline runs on top of the same coupling and handoffs that caused the instability, and nobody can show whether things improved.
At Bitcot, our engineers now start every transformation by baselining a single value stream and agreeing on its exit criteria with the leadership team before any tooling decision. That small step changes the conversation: budget reviews focus on which metric moved and why, instead of which tool was installed.
Conclusion
Enterprise DevOps transformation succeeds when it is run as a sequence of evidence-gated bets rather than a tool rollout. Baseline one value stream, give each of the seven phases an exit criterion, and judge progress with the five DORA metrics measured against that service’s own history.
The practical first move is small: choose the service where release pain is most visible, record its five metrics this month, and define what “better” means before buying anything. Once that value stream improves, you have both the playbook and the evidence to scale. If you would like a second opinion on where to start, our team is glad to walk through your current baseline with you.
Frequently Asked Questions
What is enterprise DevOps transformation?
Enterprise DevOps transformation is the organization-wide shift to a delivery system where teams own services end-to-end, infrastructure is defined as code, and delivery performance is measured continuously. It goes beyond installing DevOps tools by changing how ownership, decisions, and accountability flow across development, operations, and security.
What is the difference between DevOps adoption and DevOps transformation?
DevOps adoption means introducing tools and practices such as CI/CD pipelines, while DevOps transformation means changing the structure, ownership, and measurement of the whole delivery system. An organization can adopt DevOps and still ship large, risky releases; a transformed organization releases small changes often, recovers quickly, and proves both with the five DORA metrics.
How do I measure whether a DevOps transformation is working?
Measure it with DORA’s five delivery metrics, tracked per service against that service’s own baseline: change lead time, deployment frequency, failed deployment recovery time, change fail rate, and deployment rework rate. Improvement means throughput rises while instability falls; faster deployments with a rising rework rate signal a problem, not progress.
How are companies in San Diego and Los Angeles approaching DevOps transformation?
SaaS, fintech, and healthcare technology companies in San Diego and Los Angeles typically begin with one revenue-critical service, baseline it, and build platform engineering and pipeline security around it before scaling. The programs that stall in these markets are usually the ones that selected tools before recording a baseline.
Is enterprise DevOps transformation worth it for a mid-size company?
Yes, when it is scoped to the value streams where release problems cost the most. A mid-size company does not need to transform everything at once; baselining one service and gating each phase on measurable improvement keeps the effort proportional and shows early whether the investment is paying off.